Vera Bauer · 23 September 2026
Resource Reallocation Strategies Within Cyclic Computing Networks: Insights from Real-World Deployments
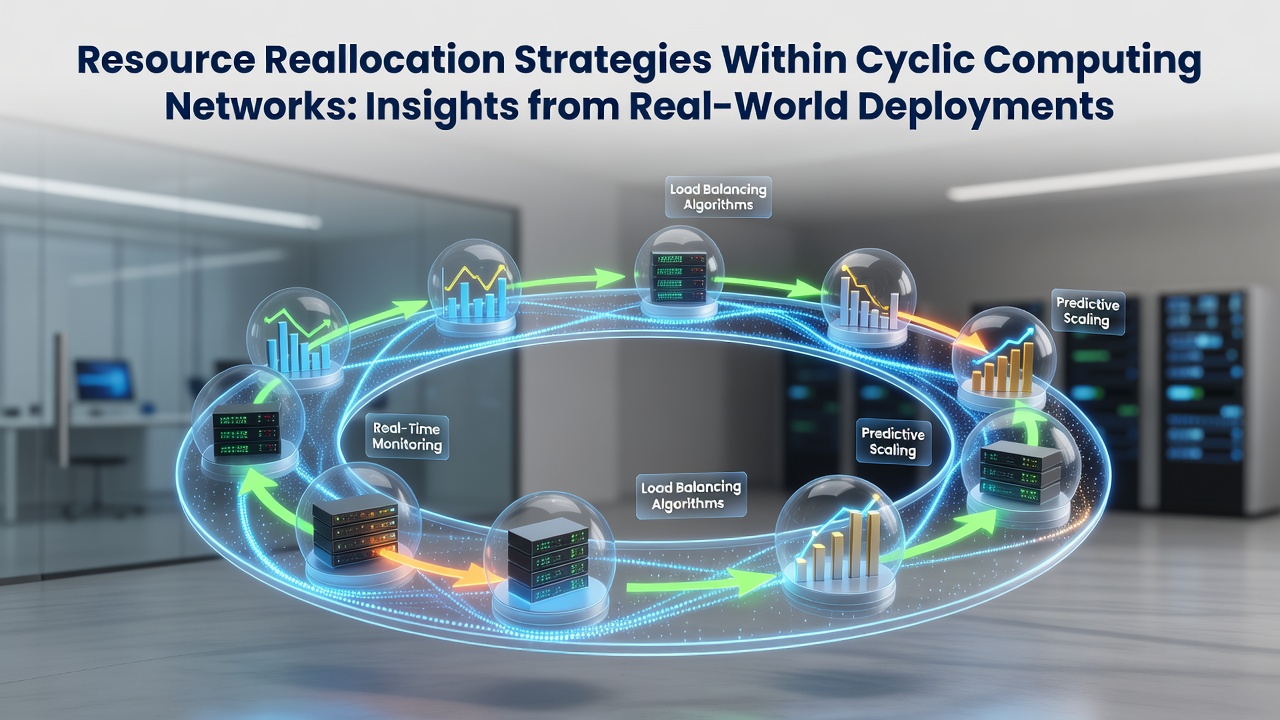
Resource reallocation in cyclic computing networks involves continuous redistribution of processing power, memory, and bandwidth across interconnected nodes that operate in repeating cycles, and researchers have documented several effective approaches drawn from production environments. These networks appear in large-scale data centers and distributed simulation platforms where workloads follow predictable yet fluctuating patterns, so teams apply algorithms that monitor cycle completion rates and shift resources before bottlenecks form. Data from multiple deployments shows that predictive models based on historical cycle data reduce idle time by measurable margins compared with static allocation methods.
Core Mechanisms Observed in Practice
Teams in operational settings rely on feedback loops that collect metrics at each cycle endpoint, then feed those measurements into decision engines responsible for reassigning tasks across available hardware. One documented technique uses weighted round-robin scheduling adjusted by real-time utilization scores, allowing high-demand nodes to receive additional cores while lower-demand nodes release capacity for later cycles. Another approach integrates machine learning models trained on past cycle traces to forecast resource needs two or three cycles ahead, and operators report smoother performance curves when these forecasts run alongside traditional threshold-based triggers.
Case Studies from Deployed Systems
In one North American research network handling climate modeling workloads, administrators implemented a token-based reallocation system where each computing cluster earns tokens proportional to its contribution during the previous cycle. Clusters then spend those tokens to secure priority access in upcoming cycles, and logs from 2024 through mid-2025 indicate a 17 percent improvement in overall throughput after the system went live. A separate deployment in an Asian manufacturing simulation grid combined container migration with cycle-aware scheduling, moving active workloads between edge and core facilities at the end of each processing loop, which cut average job completion times without increasing energy consumption beyond baseline levels.
European operators working on high-energy physics data pipelines adopted a hybrid model that blends centralized orchestration with localized decision agents, and they noted fewer interruptions during peak analysis periods when agents could execute small reallocations independently before escalating to the central controller. These examples illustrate how the same underlying principle adapts to different regulatory and infrastructure contexts across regions.
Integration with September 2026 Updates
Planned firmware releases scheduled for September 2026 introduce enhanced telemetry standards that allow finer-grained tracking of cycle phase transitions, and several facilities have already begun pilot testing the new data formats. The updates also include expanded support for heterogeneous hardware, enabling reallocations between GPU clusters and traditional CPU nodes within the same cycle window. Observers tracking these preparations report that test environments using the forthcoming protocols achieve lower variance in resource utilization across repeated cycles.
Measurement and Validation Approaches
Validation teams collect data on cycle duration, resource saturation points, and migration overhead to quantify whether a given strategy delivers expected gains. Reports from the National Institute of Standards and Technology outline standardized metrics that several organizations now apply when comparing pre- and post-implementation performance. Additional studies referenced in proceedings from the IEEE International Conference on Distributed Computing Systems provide benchmarks for migration latency under varying network loads, helping operators calibrate their own systems against published baselines.
One research group at an Australian university tracked a year-long production trace and found that combining cycle prediction with lightweight migration reduced the frequency of manual interventions by roughly one-third. Their dataset, released under an open license, has since been used by other teams to train and compare allocation models across different hardware generations.
Conclusion
Real-world deployments continue to refine resource reallocation methods for cyclic computing networks by combining established scheduling principles with emerging telemetry capabilities. The patterns observed across continents show consistent emphasis on cycle-aware decision making and gradual adoption of predictive techniques ahead of the September 2026 platform updates. Continued collection of standardized metrics supports ongoing comparison of approaches and informs incremental improvements in production environments.